Technical SEO
Why Faceted Navigation Is Killing Indexation for Enterprise E-Commerce Sites
An in-depth analysis of how faceted navigation, URL complications, robots.txt directives, canonical flows, and JavaScript-driven category pages undermine indexation in large e-commerce organizations. Focuses on commercial prioritization, Master URLs, and the direct impact of technical architecture on organic growth and revenue.
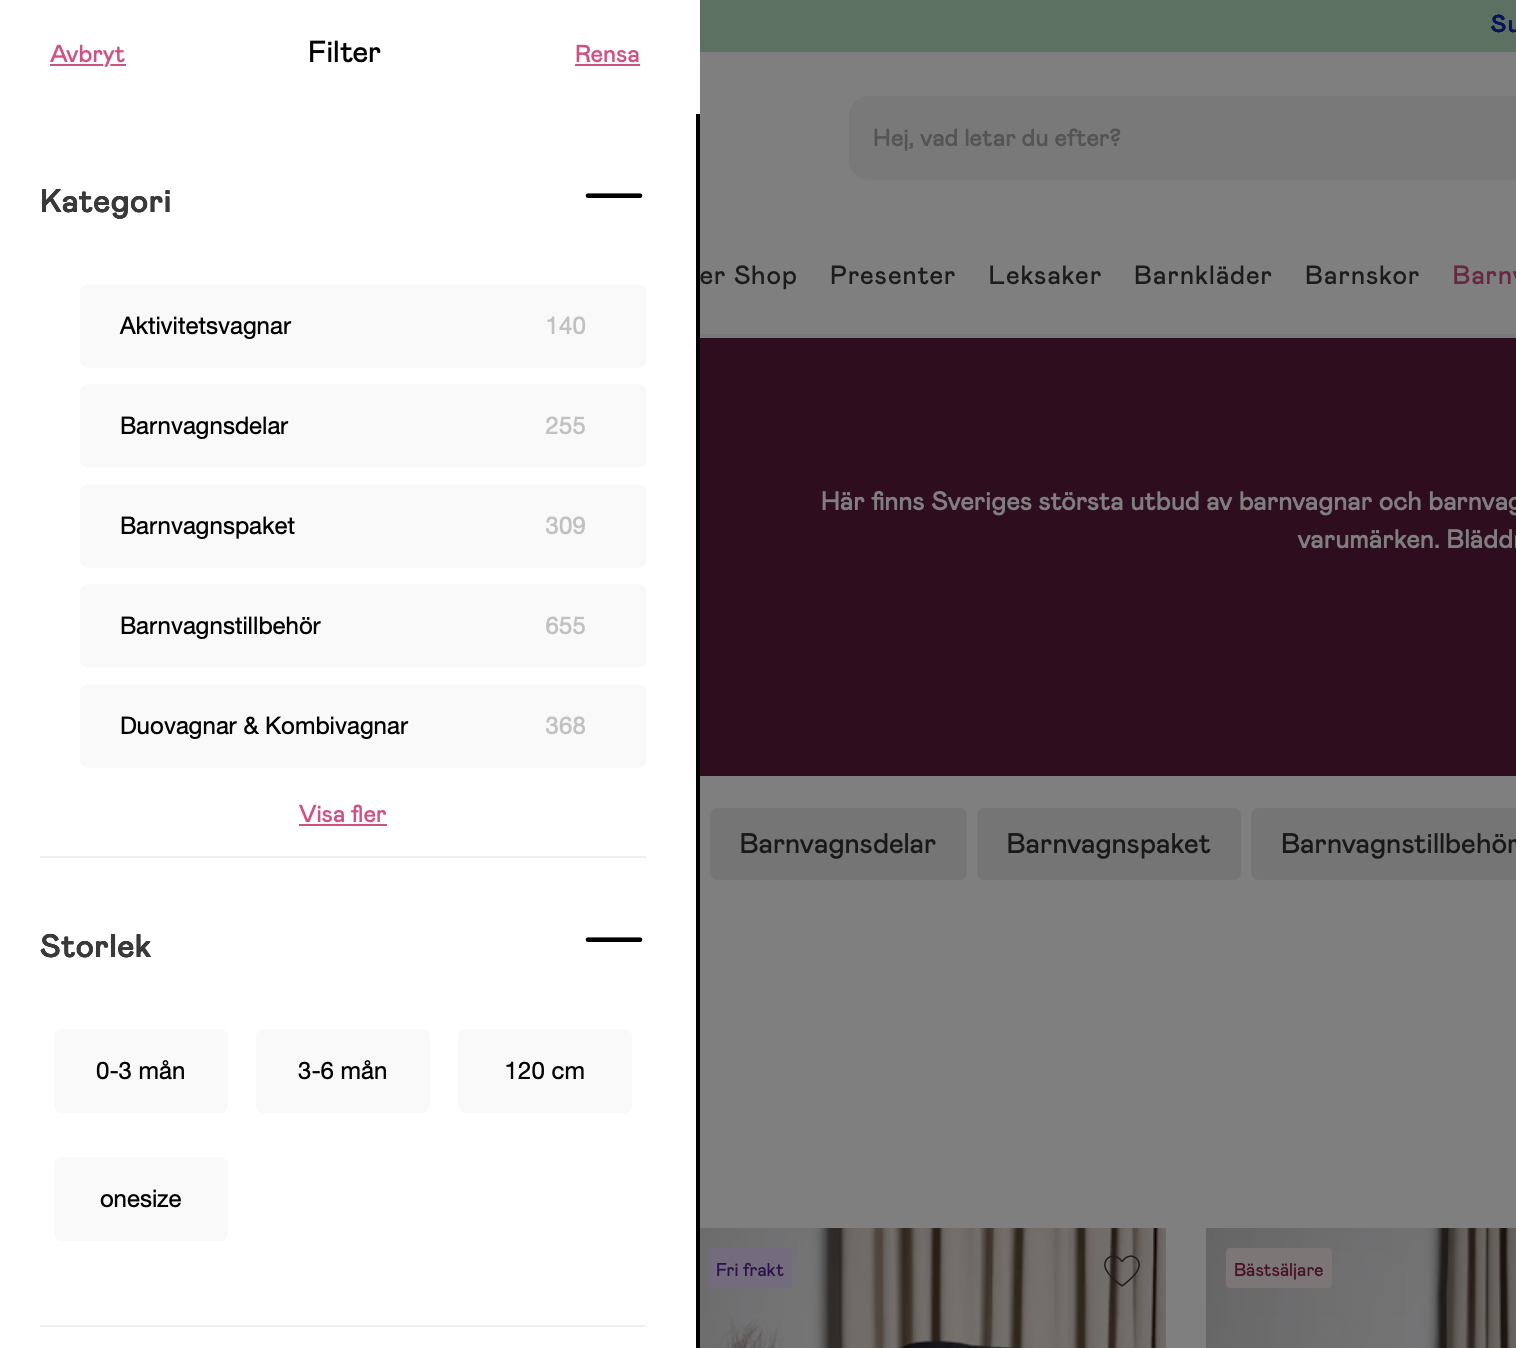
There is a widespread belief among mid-to-large e-commerce retailers that leaving every filter combination, size, and attribute open to Google boosts organic visibility. The intent is to cast a wide net to capture long-tail search traffic.
In reality, the exact opposite happens. Instead of a safety net, you build a technical swamp that is notoriously difficult to escape.
Based on my experience auditing the indexation architecture of a dozen billion-dollar e-commerce brands, companies rarely even realize this problem exists. This is not due to a lack of will, but rather because deep technical SEO expertise is either missing in-house or continuously deprioritized. As the platform scales, the content team produces, developers optimize UX, and no one in the room notices that every new attribute multiplies the underlying URL structure exponentially.
If you operate or manage an e-commerce site with tens of thousands of products and hundreds of filters, chances are Google Search Console is already flashing warnings you are overlooking. Hidden beneath the Index Generation report are often hundreds of thousands of URLs flagged as "Crawled - currently not indexed".
In plain terms, this means Google has discovered the pages but actively chosen to exclude them—mostly because they fail to provide enough unique value, or because the site has simply become too complex to interpret at scale.
This is not a cosmetic SEO issue. It is a hidden bottleneck costing you money every single day.
The In-House Blindness Halting Growth
When technical architecture becomes a blind spot, executive leadership focuses almost exclusively on top-level traffic and conversion rates. Meanwhile, SEO consultants deliver standard reports on keywords, copy, and rankings, while no one looks at how the search engine actually consumes the site.
When you add filters for color, size, material, and sorting, it triggers a mathematical explosion of URLs in the background. On a site with 20,000 products, just a few filter combinations can generate hundreds of thousands of unique URL variations. Without explicit rules to manage them, Google’s crawlers begin flying blind.
When the algorithm detects that a massive percentage of the pages it discovers are merely minor variations of the same product list, its incentive to keep exploring your structure drops. Consequently, your most commercially vital pages are pushed further away from the index—not because they lack quality, but because the overall system has become impossible to navigate.
The core challenge here isn't the technology; it's accountability.
IT/Dev owns the platform. Marketing owns the content. SEO owns the report. Faceted navigation falls squarely into the cracks between all three.
No one has the authority to veto a UX feature that improves customer filtering, even if it simultaneously guts indexation. As a result, the issue gets documented in a technical SEO audit, deprioritized in favor of a more "visible" project, and kicked down the road to the next quarter. This is precisely why e-commerce SEO breaks down before execution.
The Financial Impact on the C-Suite
A CEO or CFO is rarely going to engage with robots.txt files, canonical tags, or URL parameters. If you start preaching about "crawl budget" in the boardroom, you will lose them instantly.
What they do care about, however, is the holding cost of inventory that the market cannot find. When filter combinations are allowed to hijack Google's attention away from core pages, it triggers three direct financial penalties:
- Seasonal inventory misses the window: High-margin seasonal arrivals take too long to index because Google is stuck crawling legacy filter combinations from past seasons. By the time the products are finally discovered, the peak demand has passed, forcing steep markdowns and liquidations.
- Paid advertising becomes unnecessarily expensive: Inconsistent URL handling and feeding incorrect URLs into Merchant Center causes data matching errors. This forces you to buy Google Shopping traffic for products that should be driving free, organic conversions.
- Nimble competitors steal market share: While large enterprise organizations are bogged down in internal debates over link equity and filter logic, leaner competitors clean up their infrastructure and index their vital landing pages significantly faster.
When your high-value products sit buried behind a "Crawled - currently not indexed" status, you have effectively handed over visibility and revenue to competitors with cleaner data architecture.
Robots.txt Is Not the Enemy
If your robots.txt file only contains standard directives for admin areas, checkouts, and the like, you have likely uncovered a root cause. You are giving Google free rein to waste immense resources on millions of irrelevant filter variations.
There is an old, stubborn habit in the industry that canonical or noindex tags are enough to solve faceted navigation issues. On an enterprise scale, that approach is fundamentally flawed.
Google still has to download and process a page just to read a canonical or noindex tag. If crawlers must chew through tens of thousands of irrelevant, filtered URLs just to realize they shouldn't index them, the efficiency loss is already catastrophic.
There is also a common fear of blocking too much in robots.txt because "link equity won't pass through". But what is the actual value of link equity sent to a page that Google refuses to index anyway? Zero. Hoarding link equity on pages trapped in a swamp of unindexed bloat is like saving money in a defunct currency.
You do not want Google to analyze filters that hold no indexable value. You want them ignored entirely at the server level.
Determining What Stays Open
You should never build indexable pages just because your platform happens to generate them automatically. You build them based on commercial search intent. Not every filter combination has a right to exist in the eyes of Google.
A straightforward rule of thumb works best:
- High search volume & clear commercial intent: Keep open and index. This includes specific colors, categories, or brand pages that actively drive search demand.
- User value but zero search volume: Keep functional for the user on-site, but block entirely via
robots.txt. This typically applies to sorting by price, size, or stock status. - Technical attributes & system bloat: These should never leave the database in the first place. Internal IDs, packaging dimensions, and raw tracking parameters must be heavily blocked.
When this distinction is missing, your site architecture sends conflicting signals. A common scenario involves category trees linking to a product via one category URL, while the site simultaneously tries to point authority to a different variant using a canonical tag. Faced with this confusion, Google often ends up disregarding both.
The solution is to consolidate internal authority onto a single, clear Master URL per product. Ensure your category tree links directly to the exact version you want indexed, and redirect legacy duplicates using permanent 301 redirects. This provides a clean signal to Google and allows your top-tier products to carry their own weight.
The JavaScript Trap on Category Pages
Another structural flaw lies in how products are loaded onto category pages. Many large e-commerce sites display a limited set of initial items, requiring users to click a "Show More" button to view the rest.
While this looks sleek in design tools, it performs poorly under search engine scrutiny. If the remaining products are rendered strictly via JavaScript and the underlying architecture is flawed, Google risks only seeing the initial batch of items in the list. The rest become harder to crawl, harder to evaluate, and harder to index.
Imagine you have 120 products in a category, but Google only discovers 25 of them. The remaining 95 products exist in your database, but they do not exist in Google's world. They receive zero meaningful internal link equity, weak crawl frequency, and a severely limited chance of indexing via the primary source code.
For an e-tailer with numerous categories, this creates a systematic hemorrhage of visibility. It rarely shows up as a glaring error in a single report, but in aggregate, it costs more than major SEO initiatives.
The fix is not to compromise on aesthetics. The solution is to ensure that a sufficient number of core products are explicitly represented in the initial HTML code, allowing the search engine to map your inventory seamlessly without having to fight for it.
Cleaning Up the Infrastructure
It is time to stop treating search engines like guests who should be granted access to every dark corner of your database. They are algorithms searching for patterns, structure, and efficiency.
If you want a large-scale e-commerce site to scale organically, the solution is rarely to write more content. It is to clean up your infrastructure.
- Suffocate database bloat at the server level.
- Consolidate authority where it actually belongs.
- Ensure your most critical products live directly in the HTML without technical detours.
- Make it effortless for Google to discern what is worth indexing from what is not.
The tangible return on this investment is speed. Products that currently take months to index can begin surfacing almost instantly. Seasonal lines rank while the intent is high, ad budgets are optimized, and organic visibility becomes an asset you intentionally build—not something you merely pray for.